---
title: Programming With Effects
---
**Formatted version of the lecture notes by [Graham Hutton][0], January 2011**
Shall we be pure or impure?
---------------------------
The functional programming community divides into two camps:
- "Pure" languages, such as Haskell, are based directly
upon the mathematical notion of a function as a
mapping from arguments to results.
- "Impure" languages, such as ML, are based upon the
extension of this notion with a range of possible
effects, such as exceptions and assignments.
Pure languages are easier to reason about and may benefit
from lazy evaluation, while impure languages may be more
efficient and can lead to shorter programs.
One of the primary developments in the programming language
community in recent years (starting in the early 1990s) has
been an approach to integrating the pure and impure camps,
based upon the notion of a "monad". This note introduces
the use of monads for programming with effects in Haskell.
Abstracting programming patterns
================================
Monads are an example of the idea of abstracting out a common
programming pattern as a definition. Before considering monads,
let us review this idea, by means of two simple functions:
~~~~~{.haskell}
inc :: [Int] -> [Int]
inc [] = []
inc (n:ns) = n+1 : inc ns
sqr :: [Int] -> [Int]
sqr [] = []
sqr (n:ns) = n^2 : sqr ns
~~~~~
Both functions are defined using the same programming pattern,
namely mapping the empty list to itself, and a non-empty list
to some function applied to the head of the list and the result
of recursively processing the tail of the list in the same manner.
Abstracting this pattern gives the library function called `map`
~~~~~{.haskell}
map :: (a -> b) -> [a] -> [b]
map f [] = []
map f (x:xs) = f x : map f xs
~~~~~
using which our two examples can now be defined more compactly:
> inc = map (+1)
> sqr = map (^2)
A Simple Evaluator
------------------
Consider the following simple language of expressions that are
built up from integer values using a division operator:
> data Expr1= Val1 Int | Div1 Expr1 Expr1
Such expressions can be evaluated as follows:
> eval1 :: Expr1 -> Int
> eval1 (Val1 n) = n
> eval1 (Div1 x y) = eval1 x `div` eval1 y
> safeDiv _ 0 = Nothing
> safeDiv n m = Just (n `div` m)
> eval1' :: Expr1 -> Maybe Int
> eval1' (Val1 n) = Just n
> eval1' (Div1 x y) = case eval1' x of
> Nothing -> Nothing
> Just n1 -> case eval1' y of
> Nothing -> Nothing
> Just n2 -> n1 `safeDiv` n2
However, this function doesn't take account of the possibility of
division by zero, and will produce an error in this case. In order
to deal with this explicitly, we can use the `Maybe` type
~~~~~{.haskell}
data Maybe a = Nothing | Just a
~~~~~
to define a "safe" version of division
> safediv :: Int -> Int -> Maybe Int
> safediv n m = if m == 0 then Nothing else Just (n `div` m)
and then modify our evaluator as follows:
~~~~~{.haskell}
eval :: Expr -> Maybe Int
eval (Val n) = Just n
eval (Div x y) = case eval x of
Nothing -> Nothing
Just n -> case eval y of
Nothing -> Nothing
Just m -> safediv n m
~~~~~
As in the previous section, we can observe a common pattern, namely
performing a case analysis on a value of a `Maybe` type, mapping `Nothing`
to itself, and `Just x` to some result depending upon `x`. (*Aside*: we
could go further and also take account of the fact that the case analysis
is performed on the result of an eval, but this would lead to the more
advanced notion of a monadic fold.)
How should this pattern be abstracted out? One approach would be
to observe that a key notion in the evaluation of division is the
sequencing of two values of a `Maybe` type, namely the results of
evaluating the two arguments of the division. Based upon this
observation, we could define a sequencing function
> seqn :: Maybe a -> Maybe b -> Maybe (a,b)
> seqn Nothing _ = Nothing
> seqn _ Nothing = Nothing
> seqn (Just x) (Just y) = Just (x, y)
using which our evaluator can now be defined more compactly:
~~~~~{.haskell}
eval (Val n) = Just n
eval (Div x y) = apply f (eval x `seqn` eval y)
where f (n, m) = safediv n m
~~~~~
The auxiliary function apply is an analogue of application for `Maybe`,
and is used to process the results of the two evaluations:
~~~~~{.haskell}
apply :: (a -> Maybe b) -> Maybe a -> Maybe b
apply f Nothing = Nothing
apply f (Just x) = f x
~~~~~
In practice, however, using `seqn` can lead to programs that manipulate
nested tuples, which can be messy. For example, the evaluation of
an operator `Op` with three arguments may be defined by:
~~~~~{.haskell}
eval (Op x y z) = apply f (eval x `seqn` (eval y `seqn` eval z))
where f (a, (b, c)) = ...
~~~~~
Combining Sequencing and Processing
-----------------------------------
The problem of nested tuples can be avoided by returning of our
original observation of a common pattern: "performing a case analysis
on a value of a `Maybe` type, mapping `Nothing` to itself, and `Just x`
to some result depending upon `x`". Abstract this pattern directly gives
a new sequencing operator that we write as `>>=`, and read as "then":
~~~~~{.haskell}
(>>=) :: Maybe a -> (a -> Maybe b) -> Maybe b
m >>= f = case m of
Nothing -> Nothing
Just x -> f x
~~~~~
Replacing the use of case analysis by pattern matching gives a
more compact definition for this operator:
~~~~~{.haskell}
(>>=) :: Maybe a -> (a -> Maybe b) -> Maybe b
Nothing >>= _ = Nothing
(Just x) >>= f = f x
~~~~~
That is, if the first argument is `Nothing` then the second argument
is ignored and `Nothing` is returned as the result. Otherwise, if
the first argument is of the form `Just x`, then the second argument
is applied to `x` to give a result of type `Maybe b`.
The `>>=` operator avoids the problem of nested tuples of results
because the result of the first argument is made directly available
for processing by the second, rather than being paired up with the
second result to be processed later on. In this manner, `>>=` integrates
the sequencing of values of type `Maybe` with the processing of their
result values. In the literature, `>>=` is often called *bind*, because
the second argument binds the result of the first. Note also that
`>>=` is just apply with the order of its arguments swapped.
Using `>>=`, our evaluator can now be rewritten as:
~~~~~{.haskell}
eval (Val n) = Just n
eval (Div x y) = eval x >>= (\n ->
eval y >>= (\m ->
safediv n m))
~~~~~
The case for division can be read as follows: evaluate `x` and call
its result value `n`, then evaluate `y` and call its result value `m`,
and finally combine the two results by applying `safediv`. In
fact, the scoping rules for lambda expressions mean that the
parentheses in the case for division can freely be omitted.
Generalising from this example, a typical expression built using
the `>>=` operator has the following structure:
~~~~~{.haskell}
m1 >>= \x1 ->
m2 >>= \x2 ->
...
mn >>= \xn ->
f x1 x2 ... xn
~~~~~
That is, evaluate each of the expression `m1`, `m2`,...,`mn` in turn,
and combine their result values `x1`, `x2`,..., `xn` by applying the
function f. The definition of `>>=` ensures that such an expression
only succeeds (returns a value built using `Just`) if each `mi` in
the sequence succeeds.
In other words, the programmer does not have to worry about dealing
with the possible failure (returning `Nothing`) of any of the component
expressions, as this is handled automatically by the `>>=` operator.
Haskell provides a special notation for expressions of the above
structure, allowing them to be written in a more appealing form:
~~~~~{.haskell}
do x1 <- m1
x2 <- m2
...
xn <- mn
f x1 x2 ... xn
~~~~~
Hence, for example, our evaluator can be redefined as:
~~~~~{.haskell}
eval (Val n) = Just n
eval (Div x y) = do n <- eval x
m <- eval y
safediv n m
~~~~~
Exercise
--------
- Show that the version of `eval` defined using `>>=` is equivalent to
our original version, by expanding the definition of `>>=`.
- Redefine `seqn x y` and `eval (Op x y z)` using the `do` notation.
Monads in Haskell
=================
The `do` notation for sequencing is not specific to the `Maybe` type,
but can be used with any type that forms a *monad*. The general
concept comes from a branch of mathematics called category theory.
In Haskell, however, a monad is simply a parameterised type `m`,
together with two functions of the following types:
~~~~~{.haskell}
return :: a -> m a
(>>=) :: m a -> (a -> m b) -> m b
~~~~~
(*Aside*: the two functions are also required to satisfy some simple
properties, but we will return to these later.) For example, if
we take `m` as the parameterised type `Maybe`, `return` as the function
`Just :: a -> Maybe a`, and `>>=` as defined in the previous section,
then we obtain our first example, called the *maybe monad*.
In fact, we can capture the notion of a monad as a new class
declaration. In Haskell, a class is a collection of types that
support certain overloaded functions. For example, the class
`Eq` of equality types can be declared as follows:
~~~~~{.haskell}
class Eq a where
(==) :: a -> a -> Bool
(/=) :: a -> a -> Bool
x /= y = not (x == y)
~~~~~
The declaration states that for a type `a` to be an instance of
the class `Eq`, it must support equality and inequality operators
of the specified types. In fact, because a default definition
has already been included for `/=`, declaring an instance of this
class only requires a definition for `==`. For example, the type
`Bool` can be made into an equality type as follows:
~~~~~{.haskell}
instance Eq Bool where
False == False = True
True == True = True
_ == _ = False
~~~~~
The notion of a monad can now be captured as follows:
~~~~~{.haskell}
class Monad m where
return :: a -> m a
(>>=) :: m a -> (a -> m b) -> m b
~~~~~
That is, a monad is a parameterised type `m` that supports `return`
and `>>=` functions of the specified types. The fact that `m` must
be a parameterised type, rather than just a type, is inferred from its
use in the types for the two functions. Using this declaration,
it is now straightforward to make `Maybe` into a monadic type:
~~~~~{.haskell}
instance Monad Maybe where
-- return :: a -> Maybe a
return x = Just x
-- (>>=) :: Maybe a -> (a -> Maybe b) -> Maybe b
Nothing >>= _ = Nothing
(Just x) >>= f = f x
~~~~~
(*Aside*: types are not permitted in instance declarations, but we
include them as comments for reference.) It is because of this
declaration that the `do` notation can be used to sequence `Maybe`
values. More generally, Haskell supports the use of this notation
with any monadic type. In the next few sections we give some
further examples of types that are monadic, and the benefits
that result from recognising and exploiting this fact.
The List Monad
--------------
The maybe monad provides a simple model of computations that can
fail, in the sense that a value of type `Maybe a` is either `Nothing`,
which we can think of as representing failure, or has the form
`Just x` for some `x` of type `a`, which we can think of as success.
The list monad generalises this notion, by permitting multiple
results in the case of success. More precisely, a value of
`[a]` is either the empty list `[]`, which we can think of as
failure, or has the form of a non-empty list `[x1,x2,...,xn]`
for some `xi` of type `a`, which we can think of as success.
Making lists into a monadic type is straightforward:
~~~~~{.haskell}
instance Monad [] where
-- return :: a -> [a]
return x = [x]
-- (>>=) :: [a] -> (a -> [b]) -> [b]
xs >>= f = concat (map f xs)
~~~~~
(*Aside*: in this context, `[]` denotes the list type `[a]` without
its parameter.) That is, return simply converts a value into a
successful result containing that value, while `>>=` provides a
means of sequencing computations that may produce multiple
results: `xs >>= f` applies the function f to each of the results
in the list xs to give a nested list of results, which is then
concatenated to give a single list of results.
As a simple example of the use of the list monad, a function
that returns all possible ways of pairing elements from two
lists can be defined using the do notation as follows:
> pairs :: [a] -> [b] -> [(a,b)]
> pairs xs ys = do x <- xs
> y <- ys
> return (x, y)
That is, consider each possible value `x` from the list `xs`, and
each value `y` from the list `ys`, and return the pair `(x,y)`. It
is interesting to note the similarity to how this function
would be defined using the list comprehension notation:
~~~~~{.haskell}
pairs xs ys = [(x,y) | x <- xs, y <- ys]
~~~~~
or in Python syntax:
~~~~~{.haskell}
def pairs(xs, ys): return [(x,y) for x in xs for y in ys]
~~~~~
In fact, there is a formal connection between the `do` notation
and the comprehension notation. Both are simply different
shorthands for repeated use of the `>>=` operator for lists.
Indeed, the language *Gofer* that was one of the precursors
to Haskell permitted the comprehension notation to be used
with any monad. For simplicity however, Haskell only allows
the comprehension notation to be used with lists.
Imperative Functional Programming
---------------------------------
Consider the following *imperative* program, written in Python syntax.
~~~~~{.python}
def countEdges(xs):
prev = 0
n = 0
while (len(xs) > 0):
if xs[0] != prev:
n = n + 1
prev = xs[0]
xs = xs[1:]
return n
~~~~~
**DO IN CLASS** How would you write the above in Haskell?
The State Monad
---------------
Now let us consider the problem of writing functions that
manipulate some kind of state, represented by a type whose
internal details are not important for the moment:
~~~~~{.haskell}
type State = ...
~~~~~
The most basic form of function on this type is a *state transformer*
(abbreviated by ST), which takes the current state as its argument,
and produces a modified state as its result, in which the modified
state reflects any side effects performed by the function:
~~~~~{.haskell}
type ST = State -> State
~~~~~
In general, however, we may wish to return a result value in
addition to updating the state. For example, a function for
incrementing a counter may wish to return the current value
of the counter. For this reason, we generalise our type of
state transformers to also return a result value, with the
type of such values being a parameter of the `ST0` type:
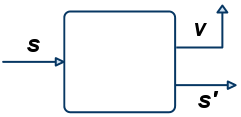
> type ST0 a = State -> (a, State)
Such functions can be depicted as follows, where `s` is the input
state, `s'` is the output state, and `v` is the result value:
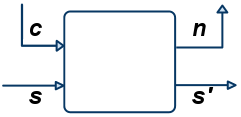
 The state transformer may also wish to take argument values.
However, there is no need to further generalise the `ST0` type
to take account of this, because this behaviour can already
be achieved by exploiting currying. For example, a state
transformer that takes a character and returns an integer
would have type `Char -> ST0 Int`, which abbreviates the
curried function type
~~~~~{.haskell}
Char -> State -> (Int, State)
~~~~~
depicted by:
 Returning to the subject of monads, it is now straightforward
to make `ST0` into an instance of a monadic type:
~~~~~{.haskell}
instance Monad ST0 where
-- return :: a -> ST0 a
return x = \s -> (x,s)
-- (>>=) :: ST0 a -> (a -> ST0 b) -> ST0 b
st >>= f = \s -> let (x,s') = st s in f x s'
~~~~~
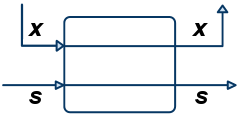
That is, `return` converts a value into a state transformer that
simply returns that value without modifying the state:
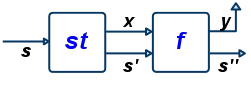
 In turn, `>>=` provides a means of sequencing state transformers:
`st >>= f` applies the state transformer `st` to an initial state
`s`, then applies the function `f` to the resulting value `x` to
give a second state transformer `(f x)`, which is then applied
to the modified state `s'` to give the final result:
 Note that `return` could also be defined by `return x s = (x,s)`.
However, we prefer the above definition in which the second
argument `s` is shunted to the body of the definition using a
lambda abstraction, because it makes explicit that `return` is
a function that takes a single argument and returns a state
transformer, as expressed by the type `a -> ST0 a`: A similar
comment applies to the above definition for `>>=`.
We conclude this section with a technical aside. In Haskell,
types defined using the `type` mechanism cannot be made into
instances of classes. Hence, in order to make ST into an
instance of the class of monadic types, in reality it needs
to be redefined using the "data" mechanism, which requires
introducing a dummy constructor (called `S` for brevity):
> data ST a = S (State -> (a, State))
It is convenient to define our own application function for
this type, which simply removes the dummy constructor:
> apply :: ST a -> State -> (a, State)
> apply (S f) x = f x
In turn, ST is now defined as a monadic type as follows:
> instance Monad ST where
> -- return :: a -> ST a
> return x = S (\s -> (x,s))
>
> -- (>>=) :: ST a -> (a -> ST b) -> ST b
> st >>= f = S (\s -> let (x,s') = apply st s in apply (f x) s')
(*Aside*: the runtime overhead of manipulating the dummy constructor
S can be eliminated by defining ST using the `newtype` mechanism
of Haskell, rather than the `data` mechanism.)
An example
----------
By way of an example of using the state monad, let us first define
a type of binary trees whose leaves contains values of some type a:
> data Tree a = Leaf a | Node (Tree a) (Tree a)
Here is a simple example:
> tree :: Tree Char
> tree = Node (Node (Leaf 'a') (Leaf 'b')) (Leaf 'c')
Now consider the problem of defining a function that labels each
leaf in such a tree with a unique or "fresh" integer. This can
be achieved by taking the next fresh integer as an additional
argument to the function, and returning the next fresh integer
as an additional result. In other words, the function can be
defined using the notion of a state transformer, in which the
internal state is simply the next fresh integer:
> type State = Int
In order to generate a fresh integer, we define a special
state transformer that simply returns the current state as
its result, and the next integer as the new state:
> fresh :: ST Int
> fresh = S (\n -> (n, n+1))
Using this, together with the `return` and `>>=` primitives that
are provided by virtue of `ST` being a monadic type, it is now
straightforward to define a function that takes a tree as its
argument, and returns a state transformer that produces the
same tree with each leaf labelled by a fresh integer:
> mlabel :: Tree a -> ST (Tree (a,Int))
> mlabel (Leaf x) = do n <- fresh
> return (Leaf (x,n))
> mlabel (Node l r) = do l' <- mlabel l
> r' <- mlabel r
> return (Node l' r')
Note that the programmer does not have to worry about the tedious
and error-prone task of dealing with the plumbing of fresh labels,
as this is handled automatically by the state monad.
Finally, we can now define a function that labels a tree by
simply applying the resulting state transformer with zero as
the initial state, and then discarding the final state:
> label :: Tree a -> Tree (a,Int)
> label t = fst (apply (mlabel t) 0)
For example, `label tree` gives the following result:
~~~~~{.haskell}
Node (Node (Leaf ('a',0)) (Leaf ('b',1))) (Leaf ('c', 2))
~~~~~
Exercise
--------
- Define a function `app :: (State -> State) -> ST State`, such
that fresh can be redefined by `fresh = app (+1)`.
- Define a function `run :: ST a -> State -> a`, such that label
can be redefined by `label t = run (mlabel t) 0`.
The IO Monad
============
Recall that interactive programs in Haskell are written using the
type `IO a` of "actions" that return a result of type `a`, but may
also perform some input/output. A number of primitives are
provided for building values of this type, including:
~~~~~{.haskell}
return :: a -> IO a
(>>=) :: IO a -> (a -> IO b) -> IO b
getChar :: IO Char
putChar :: Char -> IO ()
~~~~~
The use of return and `>>=` means that `IO` is monadic, and hence
that the do notation can be used to write interactive programs.
For example, the action that reads a string of characters from
the keyboard can be defined as follows:
~~~~~{.haskell}
getLine :: IO String
getLine = do x <- getChar
if x == '\n' then
return []
else
do xs <- getLine
return (x:xs)
~~~~~
It is interesting to note that the `IO` monad can be viewed as a
special case of the state monad, in which the internal state is
a suitable representation of the "state of the world":
~~~~~{.haskell}
type World = ...
type IO a = World -> (a,World)
~~~~~
That is, an action can be viewed as a function that takes the
current state of the world as its argument, and produces a value
and a modified world as its result, in which the modified world
reflects any input/output performed by the action. In reality,
Haskell systems such as Hugs and GHC implement actions in a more
efficient manner, but for the purposes of understanding the
behaviour of actions, the above interpretation can be useful.
Derived primitives
==================
An important benefit of abstracting out the notion of a monad
is that it then becomes possible to define a number of useful
functions that work in an arbitrary monad. For example, the
`map` function on lists can be generalised as follows:
> liftM :: Monad m => (a -> b) -> m a -> m b
> liftM f mx = do x <- mx
> return (f x)
Similarly, `concat` on lists generalises to:
> join :: Monad m => m (m a) -> m a
> join mmx = do mx <- mmx
> x <- mx
> return x
mmx >>= id
It is sometimes useful to sequence two monadic expressions,
but discard the result value produced by the first:
~~~~~{.haskell}
(>>) :: Monad m => m a -> m b -> m b
mx >> my = do _ <- mx
y <- my
return y
~~~~~
For example, in the state monad the `>>` operator is just normal
sequential composition, written as `;` in most languages.
As a final example, we can define a function that transforms
a list of monadic expressions into a single such expression that
returns a list of results, by performing each of the argument
expressions in sequence and collecting their results:
~~~~~{.haskell}
sequence :: Monad m => [m a] -> m [a]
sequence [] = return []
sequence (mx:mxs) = do x <- mx
xs <- sequence mxs
return (x:xs)
~~~~~
Exercise
--------
- Define `liftM` and `join` more compactly by using `>>=`.
- Explain the behaviour of sequence for the maybe monad.
- Define another monadic generalisation of map:
~~~~~{.haskell}
mapM :: Monad m => (a -> m b) -> [a] -> m [b]
~~~~~
- Define a monadic generalisation of foldl:
~~~~~{.haskell}
foldM :: Monad m => (a -> b -> m a) -> a -> [b] -> m a
~~~~~
The monad laws
==============
Earlier we mentioned that the notion of a monad requires that the
return and `>>=` functions satisfy some simple properties. The
first two properties concern the link between return and `>>=`:
~~~~~{.haskell}
return x >>= f = f x -- (1)
mx >>= return = mx -- (2)
~~~~~
Intuitively, equation (1) states that if we return a value `x` and
then feed this value into a function `f`, this should give the same
result as simply applying `f` to `x`. Dually, equation (2) states
that if we feed the results of a computation `mx` into the function
return, this should give the same result as simply performing `mx`.
Together, these equations express --- modulo the fact that the
second argument to `>>=` involves a binding operation --- that
return is the left and right identity for `>>=`.
The third property concerns the link between `>>=` and itself, and
expresses (again modulo binding) that `>>=` is associative:
~~~~~{.haskell}
(mx >>= f) >>= g = mx >>= (\x -> (f x >>= g)) -- (3)
~~~~~
Note that we cannot simply write `mx >>= (f >>= g)` on the right
hand side of this equation, as this would not be type correct.
As an example of the utility of the monad laws, let us see how
they can be used to prove a useful property of the `liftM` function
from the previous section, namely that it distributes over the
composition operator for functions, in the sense that:
~~~~~{.haskell}
liftM (f . g) = liftM f . liftM g
~~~~~
This equation generalises the familiar distribution property of
map from lists to an arbitrary monad. In order to verify this
equation, we first rewrite the definition of `liftM` using `>>=`:
~~~~~{.haskell}
liftM f mx = mx >>= \x -> return (f x)
~~~~~
Now the distribution property can be verified as follows:
~~~~~{.haskell}
(liftM f . liftM g) mx
= {- applying . -}
liftM f (liftM g mx)
= {- applying the second liftM -}
liftM f (mx >>= \x -> return (g x))
= {- applying liftM -}
(mx >>= \x -> return (g x)) >>= \y -> return (f y)
= {- equation (3) -}
mx >>= (\z -> (return (g z) >>= \y -> return (f y)))
= {- equation (1) -}
mx >>= (\z -> return (f (g z)))
= {- unapplying . -}
mx >>= (\z -> return ((f . g) z)))
= {- unapplying liftM -}
liftM (f . g) mx
~~~~~
Exercise
--------
Show that the maybe monad satisfies equations (1), (2) and (3).
Exercise
--------
Given the type
> data Expr a = Var a | Val Int | Add (Expr a) (Expr a)
of expressions built from variables of type `a`, show that this
type is monadic by completing the following declaration:
~~~~~{.haskell}
instance Monad Expr where
-- return :: a -> Expr a
return x = ...
-- (>>=) :: Expr a -> (a -> Expr b) -> Expr b
(Var a) >>= f = ...
(Val n) >>= f = ...
(Add x y) >>= f = ...
~~~~~
Hint: think carefully about the types involved. With the aid of an
example, explain what the `>>=` operator for this type does.
Other topics
------------
The subject of monads is a large one, and we have only scratched
the surface here. If you are interested in finding out more,
two suggestions for further reading would be to look at "monads
with a zero a plus" (which extend the basic notion with two
extra primitives that are supported by some monads), and "monad
transformers" (which provide a means to combine monads.) For
example, see sections 3 and 7 of the following article, which
concerns the monadic nature of [functional parsers][3]
For a more in-depth exploration of the IO monad, see Simon Peyton
Jones' excellent article on the ["awkward squad"][2]
[0]: http://www.cs.nott.ac.uk/~gmh/monads
[1]: http://en.wikipedia.org/wiki/Gofer_(software) "Gofer Language"
[2]: http://research.microsoft.com/Users/simonpj/papers/marktoberdorf/ "Awkward Squad"
[3]: http://www.cs.nott.ac.uk/~gmh/monparsing.pdf "Functional Parsers"