| Date | Description |
| 20-Jan-11 | Original posting |
| 30-Jan-11 | Thread geometry arguments corrected to -x -y. |
In this assignment you'll apply multithreading to a simulator used to study the electrophysiology of the heart, and observe parallel speedups. A working serial version of the code has been provided on ieng6-203 in $PUB/HW/A2, where $PUB is defined as
/home/linux/ieng6/cs160w/public
Owing to higher memory bandwidth demands, this application will not scale nearly as well as the primality testing application in assignment #1. Thus, it provides ample motivation for performance programming. Try to make the code go as fast as you can.
You may develop code on another machine if you wish but be sure and confirm all results on ieng6-203.ucsd.edu, as your assignment will be graded against behavior on that machine.
Simulations play an important role in science, medicine, and engineering. For example, a cardiac electrophysiology simulator can be used for clinical diagnostic and therapeutic purposes. To reduce computational costs, simplifying assumptions are often made to make the simulations practical. In our clinical example, time may be of the essence in determining an appropriate life-saving treatment.
Cell simulators entail solving a coupled set of a equations: a system of Ordinary Differential Equations (ODEs) together with a Partial Differential Equation (PDE). If you are interested in learning more about cardiac modeling peruse www.labheart.org or thevirtualheart.org or visit the web page of the UCSD Cardiac Mechanics Research Group.
Our simulator models the propagation of electrical signals in the heart, and it incorporates a cell model describing the kinetics of the membrane of a single cell. There can be different cell models, of varying degrees of complexity. We will use a model known as the Aliev-Panfilov model, that maintains 2 state variables, and solves one PDE (The PDE couples multiple cells into a system). This simple model can account for complex behavior such as how spiral waves break up and form elaborate patterns. Spiral waves can lead to life threatening situations such as ventricular fibrillation.
Our simulator models electrical signals in an idealized biological system in which voltages vary at discrete points in time, called timesteps, at the discrete positions of a mesh. The simulator is an iterative procedure that updates the simulation state variables (on the mesh) many times over a sequence of discrete timesteps.
A simulation will run for some amount of simulated time, which is a real number. For our purposes, the units of time are unimportant. These timesteps subdivide the simulation time line that starts at t=0 and ends at some specified time t=T. The unit of subdivision is called Δt, or the time discretization. It is important to keep in mind that when we use the term "time," we need to specify whether we are talking about real-valued simulation time, or the discrete timestep. By convention, we number the discrete timesteps with integers. Thus, if we say that we are at timestep k, then the current simulation time is kΔt.
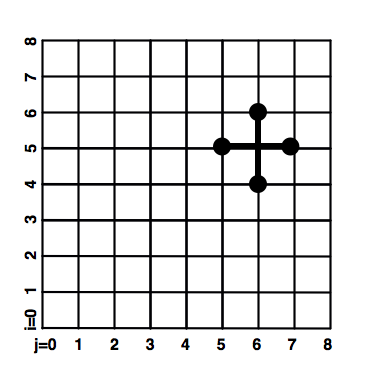
To discretize space, we'll use a uniformly spaced two-dimensional mesh, shown in the left side of the figure (Irregular meshes are also possible, but are more difficult to parallelize).
|
|
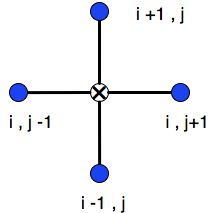
At each time step, the simulator updates the voltage according to nearest neighboring positions in space and time. This is done first in space, and next in time. Nearest neighbors in space are defined on the 4 Manhattan directions only: north, south, east and west as shown on the right side of the above figure.
In general, the finer the mesh (and hence the more numerous the points) the more accurate the solution, but for an increased computational cost. In a similar fashion, the smaller the timestep, the more accurate the solution, but at a higher computational cost. Thus, if h is the mesh spacing, Δt is the time discretization, then the running time is proportional to (Δt×h2)-1.
The simulator maintains two state variables characterizing the cell electrophysiology model: excitation (E) and recovery (R). Since we are using the method of finite differences to solve the problem, we discretize the variables E and R by considering the values only at a regularly spaced set of discrete points. We represent the variables as 2D arrays: E[][] and R[][], respectively. The PDE solver also maintains the voltage at the previous timestep, Eprev.
Here is the formula for solving the PDE, where the superscripts t and t-1 refer to the current and previous timestep, respectively, and the constant α is defined in the simulator (see apf.cpp and solve.cpp):
Et[i,j] = Et-1[i,j] + α*(Et-1[i+1,j] + Et-1[i-1,j] + Et-1[i,j+1] + Et-1[i,j-1] - 4*Et-1[i,j])
Here is the formula for solving the ODE, where references to E and R correspond to whole arrays, expressions involving whole arrays are pointwise operations involving corresponding array elements, and the constants k, a, b, ε, μ1 and μ2 are defined in the simulator:
E = E - Δt*(k*E * (E-a) * (E-1)+E * R);
R = R + Δt*(ε+ μ1*R / ( E+μ2)) * (-R-k*E * (E-b-1));
We interpret a pointwise array operation as follows. If A, B and C are arrays of length N, then A = B + C is equivalent to the following loop:
for (i = 0; i < N; i++)
  A[i] = B[i] + C[i];
There are a few bookkeeping details needed to help us organize our work. We divide each axis into N-1 subintervals using N points positioned uniformly along the line at positions x=i×h, i=0, 1, 2, ..., N-1. This is shown in below, for 1 axis of the mesh drawn above , where the mesh spacing h = 1/N
i=0   i=1   i=2                      i=N-1
|-----|-----|------| ..... |-----|-----|
^                                      ^
|                                      |
x=0   x=h  x=2h                 x=1-h  x=1
You'll notice that the solution arrays in the simulator have 2 extra cells in each dimension (the -n parameter + 1). We pad the arrays to add space to help us take derivatives on the physical boundary. This padding will simplify the code and you'll see comments about it in solve.cpp.
Consider the case where we set n=64. We allocate an array of size 67 × 67, but we solve the problem on a central 65 × 65 submesh. Thus, our loops range from 1 to n+1, that is, 1 to 65. Points 0 and 66 correspond to buffer points.
It follows that when we subdivide the data to partition it for parallel execution, we are actually subdividing n+1 rather than n. You must handle the general case where n+1 is not evenly divisible by the number of threads.
The code for a working serial simulator has been installed in ieng6-203 in $PUB/HW/A2. Most (or all) of your changes will made in two files: apf.cpp, which is the driver program, and solver.cpp, containing the solve() function. This solver is computationally intensive, so most of your efforts will efforts on improving its running time through multithreading, and possibly some performance programming.
The organization of the code is described in a README file. Be sure to look over this file so you are familiar with the various code modules. To ensure that your program is correctly graded, do not change any of the following 7 files, as doing so may cause your turnin to be graded incorrectly:
cmdLine.cpp Report.cpp Timer.cpp parTimer.cpp splot.c apf.h types.h
The simulator driver is found in apf.cpp, but the numerical computation is handled in solver.cpp. Command line arguments are parsed in cmdLine.cpp While not used in the serial code, additional arguments have also been provided for specifying the thread geometry: -x and -y. We have also provided a script file with the public tests that we will use to test your code: run.sh
To build your code, use the provided Makefile, as it sets up the appropriate flags for the Gnu compiler via the "arch" file located in $(PUB)/Arch/arch.gnu.pthread. (At the moment we are using version 4.1.2 of gcc and g++, so keep this in mind if you are trying to develop your code on another machine.) The Makefile produces a target called apf. Do not change the name of this target. You may add additional code files if you wish, or change the names of the object files, except for the files mentioned above.
The simulator takes various command line options as follows.
./apf [-t <simulation time>] [-n < box size >] [-s] [-p <plot freq>]
The default parameters are described in cmdLine.cpp:
| -t <float> | Duration of simulation |
| -n <integer> | Number of mesh points in the x and y dimensions |
| -s | Print statistics, L2 and L∞ norms of the excitation variable. This feature is useful when debugging. |
| -p <integer> | Plot the excitation variable at regular intervals. This feature is also useful in debugging. |
Thus, the command line
./apf -n 150 -t 400 -s -p 20
will conduct the simulation on a 150 × 150 box, run to 400 units of simulated time, plot the excitation variable every 20 units of simulated time, and periodically print out summary values of the excitation variable (The code is set up to print out the statistics every 100 units of simulated time, and the frequency can be changed by appropriately setting the value of the STATS_FREQ variable as noted in apf.cpp).
If we leave off the -s and -p flags, then the output is as follows:
./apf -n 150 -t 400
[Simulation begins] Sun Jan 16 21:05:37 2011

Using Double precision arithmetic
dt= 0.0636729, T = 400
The code will run for approximately 6283 timesteps
m x n = 150 x 150
thread geometry: 1 x 1

[Simulation completes] Sun Jan 16 21:05:46 2011

End at time: 400, iteration 6283
Max norm: 9.41928e-01, L2norm: 6.11817e-01
Running Time: 9.00787 sec.
GFlop rate: 0.445
Parallelize the code with pthreads, letting one of the threads handle the plotting. This introduces an obvious bottleneck, but we can live with it. In exchange you will have output that is useful when testing and debugging.
Be careful about synchronization. Other than forking and joining of threads, all synchronization is confined to the solve.cpp file, which includes the code to compute summary statistics.
Implement 1-dimensional partitioning only. There are two possible 1-dimensional partitionings--horizontal and vertical-- and your code must support both of them. Specify the partitionings via the thread geometry command line arguments -x -y. Does one partitioning lead to higher performance?
Your code must correctly handle the case when the number of threads doesn't evenly divide the size of the mesh. It must divide the mesh as evenly as possible using partitionings that have the following property.
The amount of work assigned to the most heavily and most lightly-loaded threads differs by not more than one row (or column) of the array.
You may assume that
n > 2 × the number of threads
Try to make the code go as fast as you can. In the spirit of friendly competition, post your performance results to the A2 Moodle forum.
We will grade your machine on ieng6-203.ucsd.edu. Be sure to do your final testing on that machine, to avoid any surprises at turnin time.
Your code will be tested for correctness and performance. When grading your assignment, we will test your code against one public input (in the script file run.sh) plus other inputs that will not be made public. Be sure to test against various combinations of the -n and -t command line parameters. There is no need for your program to run for more than about 15 or 20 seconds.
Test your code by comparing against the provided implementation. You can catch obvious errors using the graphical output, but a more precise test is to compare two summary quantities reported by the simulator: the L2 norm and maximum value (magnitude) of the excitation variable. The former value is obtained by summing the squares of all solution values on the mesh, dividing by the number of points in the mesh (called normalization), and taking the square root of the result. For latter measure, we take the "absolute max," that is the maximum of the absolute value of the solution. While there may be slight variations in the last digits of the reported quantities, variations in the first few digits indicate an error.
To test your code for correctness, vary the number of threads and experiment with vertical and horizontal partitioning. Verify that results are independent of the number of threads and the chosen partitioning (try both vertical and horizontal). Your code must correctly handle the case when the number of threads doesn't evenly divide the size of the mesh as described previously.
To validate correctness use the output shown previously. In particular, for the command line options
-n 50 -t 1000
your output should contain the following two consecutive lines:
End at time: 1000, iteration 11495
Max:   9.46128e-01, L2norm:   6.15442e-01
You are also required to speed up the application. While the application will not attain perfect scaling as in the previous assignment, you should observe a speedup to at least 4 cores. Try larger values of the n parameter. When you do this you'll need to adjust the -T parameter downward; the simulation will take much longer to complete, not only because it is doing more work on a larger mesh, but also because it needs to reduce Δt, the discrete timestep, to ensure accuracy. Thus, your simulator is performing a larger number of mesh sweeps on larger meshes. Do you notice any change in scaling as you increased n?
Be sure that, while collecting performance data, that you have not enabled plotting (-p) or statistics reporting (-s).
To facilitate testing, the simulator outputs some essential information into a file called Log.txt: the number of threads, their geometry, the running time, and the L2 and L∞ norms. We will use this file in autograding so do not change the file Report.cpp as doing so could cause your assignment to be graded incorrectly. Any previous copy of Log.txt will be overwritten, so if you are doing automated testing, be sure to rename the files between invocations.
Use the provided timer to take timings. Run the program at least 3 times -- for each input size or any other variable that affects the running time -- until you see a consistent timing emerge, that is, where a majority of the times agree to within 10%. If you do not observe a consensus, try doubling the number of measurements. Exclude outlying timings (but note how large they are).
If the system is heavily loaded, as in the day the assignment is due, you may observe performance anomalies, including non-linear speedups. Try testing at another time of day. The at(1) command, described in the last assignment, enables you to schedule a job to run at a pre-determined time, say, in the middle of the night. The output will be mailed to your ACS mailbox.
We have provided high resolution timers based on gettimeofday(). The timer in Timer.cpp allows you to time a individual threads and you can see how it is used in the provided serial code. Recall that the running time of the application is determined by the last core to finish. Consequently, we have provided a variant of the timer in parTimer.cpp, that uses barrier synchronization to ensure that we correctly account for that last thread. To use this timer, you must initialize some internal state (the barrier). Make the following call exactly once prior to spawning your threads
initTimer(NT);
where NT is the number of threads. When you are finished using the timer, and all spawned threads have been joined, invoke FinalizeTimer() exactly once.
As mentioned previously, The code comes with a plotting capability to observe the simulation dynamics which can be helpful when debugging. The plotter (splot.c) interfaces with gnuplot, which is freeware.
Remote visual display can be slow, so use a frequency of at least 20. The summary statistics may be more useful than plotting in some cases. If a display window does not appear on your screen, then your ssh display settings are not set correctly. If you are connecting to ieng6-203 from a Linux platform using ssh, use the -X option:
% ssh -X yourlogin@ieng6-203.ucsd.edu
If you are connecting from a Windows platform, and are using a 'secure shell client' AND 'exceed' (or xwin32, or cygwin) to log into ieng6-203.ucsd.edu, then you must ensure that 'X11 tunneling' is set. To do this, you must have installed Cygwin /X with X11.
The simulations will produce a spiral pattern that is pleasing to the eye. However, if you set the simulation time parameter (-T) to a sufficiently large value, the nice spiral pattern will break up. This indicates non-physical behavior, and the length of time that the simulator produces physically meaningful results depends on the mesh size n.
Turn in your source code electronically not later than the deadline at 9pm on the day the assignment is due. We will provide instructions about the electronic turnin procedure on Moodle.
The timestamp on the electronic turnin establishes the time that you handed in the assignment, and successive turnins will overwrite any existing turnin. Once the deadline has passed (with a few minutes' grace period), you will not be able to turn in your assignment. Be careful to turn in on time.
Important Note: Since the turnin script will try to compile your project before letting you submit your assignment, it's important that you turn in all the files you have. However, when grading your assignment, we will substitute all the files that you are not allowed to modify (as noted in the list above) with the original copies of the version we provided you. This is why it is important that you do not change those files in your own turnin, as they will be lost.
Don't wait until the last minute to attempt a turnin for the first time. The turnin program will ask you various questions, and it will check for the presence of certain required files, as well as your source code. It will also build the source code if you like, to catch any obvious build errors. Try out the turnin process early on so you are sure that you you are familiar with the process, and that all the required additional files are present.
Your turnin must include a valid team self-evaluation discussing the division of labor and other aspects of how you worked together as a team. A copy of the form is available in $PUB/turnin/teameval.txt. This form is mandatory, as the turnin process will not complete without it. You must also provide a MEMBERS file that identifies your team members, with your full names and email addresses. A template showing the format can be found in $PUB/turnin/MEMBERS. Empty forms, or formed not diligently fill out, will result in a 10% penalty being assessed, in addition to holding up the grading process.
Copyright © 2011 Scott B. Baden Fri [Tue Jan 18 20:50:33 PST 2011]