| Date | Description |
| 4-Nov-12 | Original posting |
| 7-Nov-12 | Added a note about MPI+X programming |
| 11-Nov-12 | Added a note about coding conventions |
In this assignment you'll implement the heart electrophysiology simulator discussed in class using the Message Passing Interface, MPI, and run on the Bang cluster. For instructions about how to compile and run MPI jobs on Bang, refer to the document Using MPI on Bang.
The assignment includes a report, and the requirements for this report are described below. As with A1, you'll submit a hard copy lab report and also turn in your assignment (code + report) electronically on Bang. We will announce, via the A3 Moodle forum, when the turnin program has been enabled.
Simulations play an important role in science, medicine, and engineering. A simulator like the cardiac electrophysiology simulator we are using in this assignment can be used for clinical diagnostic and therapeutic purposes. To reduce computational costs, simplifying assumptions are often made to make the simulations feasible. In our clinical example, time may be of the essence in determining an appropriate life-saving treatment.
Cell simulators entail solving a coupled set of a equations: a system of Ordinary Differential Equations (ODEs) together with a Partial Differential Equation (PDE). If you are interested in learning more about cardiac modeling peruse www.labheart.org or thevirtualheart.org or visit the web page of the UCSD Cardiac Mechanics Research Group.
Our simulator models the propagation of electrical signals in the heart, and it incorporates a cell model describing the kinetics of the membrane of a single cell. There can be different cell models, of varying degrees of complexity. We will use a model known as the Aliev-Panfilov model, that maintains 2 state variables, and solves one PDE (The PDE couples multiple cells into a system). This simple model can account for complex behavior such as how spiral waves break up and form elaborate patterns. Spiral waves can lead to life threatening situations such as ventricular fibrillation.
Our simulator models electrical signals in an idealized biological system in which voltages vary at discrete points in time, called timesteps, at the discrete positions of a mesh. The simulator is an iterative procedure that updates the simulation state variables (on the mesh) many times over a sequence of discrete timesteps. A simulation will run for some amount of simulated time, which is a real number. (For our purposes, the units of time are unimportant.) The timesteps subdivide the simulation time line that starts at t=0 and ends at some specified time t=T. The unit of subdivision is called Δt, or the time discretization. It is important to keep in mind that when we use the term "time," we need to specify whether we are talking about real-valued simulation time, or the discrete timestep. We will use the fully qualified name to avoid ambiguity. By convention, we number the discrete timesteps with integers. Thus, if we say that we are at timestep k of the simulation, then the current simulation time is kΔt.
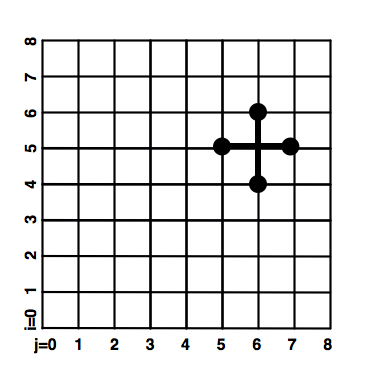
To discretize space, we'll use a uniformly spaced two-dimensional mesh, shown in the left side of the figure (Irregular meshes are also possible, but are more difficult to parallelize).
|
|
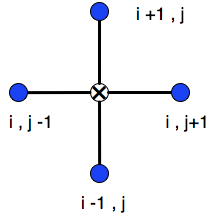
At each time step, the simulator updates the voltage according to nearest neighboring positions in space and time. This is done first in space, and next in time. Nearest neighbors in space are defined on the 4 Manhattan directions only: north, south, east and west as shown on the right side of the above figure.
In general, the finer the mesh (and hence the more numerous the points) the more accurate the solution, but at an increased computational cost. In a similar fashion, the smaller the timestep, the more accurate the solution, but at a higher computational cost. Thus, if h is the mesh spacing, Δt is the time discretization, then the running time is proportional to (Δt×h2)-1. However, to simplify our performance studies, we will run our simulations for a given number of iterations rather than a given amount of simulated time.
The simulator maintains two state variables characterizing the cell electrophysiology model: excitation (E) and recovery (R). Since we are using the method of finite differences to solve the problem, we discretize the variables E and R by considering the values only at a regularly spaced set of discrete points. We represent the variables as 2D arrays: E[][] and R[][], respectively. The PDE solver also maintains the voltage at the previous timestep, Eprev.
Here is the formula for solving the PDE, where the superscripts t and t-1 refer to the current and previous timestep, respectively, and the constant α is defined in the simulator (see apf.cpp and solve.cpp):
Et[i,j] = Et-1[i,j] + α*(Et-1[i+1,j] + Et-1[i-1,j] + Et-1[i,j+1] + Et-1[i,j-1] - 4*Et-1[i,j])
Here is the formula for solving the ODE, where references to E and R correspond to whole arrays. Expressions involving whole arrays are pointwise operations on corresponding array elements, and the constants k, a, b, ε, μ1 and μ2 are defined in the simulator:
E = E - Δt*(k*E * (E-a) * (E-1)+E * R);
R = R + Δt*(ε+ μ1*R / ( E+μ2)) * (-R-k*E * (E-b-1));
We interpret a pointwise whole array operation as follows. If A, B and C are 2D arrays of size N × N, then A = B + C is equivalent to the following loop nest:
for (i = 0; i < N; i++)
    for (j = 0; j < N; j++)
        A[i][j] = B[i][j] + C[i][j];
To organize our work, we observe a number of bookkeeping conventions. We divide each axis into N-1 subintervals using N points positioned uniformly along the line at positions x=i×h, i=0, 1, 2, ..., N-1. We also pad the boundaries with a cell on each side, in order to properly handle updates next to a boundary. (This padding will simplify the code and you'll see comments about it in solve.cpp.) This is shown in below, for 1 axis of the mesh drawn above, where the mesh spacing h = 1/N. The points labeled 'o' correspond to the physical boundary, the points labeled 'P' are padding.
i=0   i=1    i=2                    i=N-1   i=N   i=N+1
P------o------|------| ...... |------|------|------o------P
       ^                                           ^
       |                                           |
      x=0.0  x=h    x=2h                 x=1.0-h   x=1.0
Consider the case where we set N=64. We allocate an array of size 67 × 67, but we solve the problem on a central 65 × 65 submesh. Thus, our loops range from 1 to N+1, that is, 1 to 65. Points 0 and 66 correspond to buffer points.
It follows that when we subdivide the data to partition it for parallel execution, we are actually subdividing N+1 rather than N.
A working serial version of the Aliev Panfilov code has been provided on Bang in $PUB/HW/A3. The code includes some basic calls to MPI to get you started. We have also provided a batch script file, batch_bang.sh.
Most (or all) of your changes will made to two files: apf.cpp, the driver program, and solve.cpp, containing the solve() function. The solver is computationally intensive, so the focus of your parallelization and performance programming effort will be on this routine.
To build your code, use the provided Makefile, as it sets up the appropriate flags for the compiler via the "arch" file located in $(PUB)/Arch/arch.gnu.generic. The Makefile produces a target called apf. Do not change the name of this target. You may add additional code files if you wish, but to ensure that your program is correctly graded, do not change any of the following files:
cmdLine.cpp Report.cpp Timer.cpp apf.h types.h
The simulator has various options, controlled via command line arguments (parsed in in cmdLine.cpp), with default values set in apf.cpp:
| -n <int> | Number of mesh points in the x and y dimensions |
| -i <int> | Duration of simulation in iterations |
| -s <int> | Print statistics, L2 and L∞ norms of the
excitation variable at specified regular intervals (in timesteps).
This feature is useful when debugging. |
| -p <int> | Plot the excitation variable, at the specified regular intervals (in timesteps). Useful when debugging. |
| -x <int> -y <int> |
x and y-axis of the the processor geometry (Used only for your MPI implementation) |
| -k | Disable communication (Used only for your MPI implementation) |
Thus, the following command line will conduct the simulation on a 150 × 150 box, run for 400 iterations, plot the excitation variable every 20 iterations, and print out summary values of the excitation variable every 10 iterations.
./apf -n 150 -i 400 -s -10 -p 20
If we leave off the -s and -p flags, then the output is as follows. The last line of output, beginning with the string "#>" outputs performance data along with relevant parameters, that is suitable for automated extraction from a sequence of runs.
[Simulation begins] Sun Nov  4 09:44:07 2012
Using Double precision arithmetic
dt= 0.0636729, # iters = 400
m x n = 150 x 150
processor geometry: 1 x 1
Compiled with MPI ENabled
[Simulation completes] Sun Nov  4 09:44:07 2012
End at iteration 400
Max norm: 9.928177e-01, L2norm: 6.128517e-01
Running Time: 0.223005 sec.
GFlop rate: 1.15
  M x N, [px x py, NT] [#iter] {T_p, Gflops} Linf, L2
># 150 150 [1 1 1] 	[ 400] {0.223 1.145} 9.92818e-01 6.12852e-01
The plotting capability, controlled via the -p flag, uses gnuplot, and may be useful in debugging. Do not enable plotting when you are measuring running times for your performance studies. The plotter capability only works on a single core and is discussed in more detail later in this writeup.
You'll notice that the provided code uses a different naming convention for the bounds of the computational box. In particular, while we use the single letter N in this document, the code uses different bounds, for the x and y axes, in terms of variables m and n. This convention enables the code to accomodate non-square local problem sizes that arise when the data has been partitioned for parallel execution. You'll also note that the computational boxes are padded by one cell in each dimension (in alloc2D()). This change is made to handle boundary conditions, and is described in solve()
Try to make your code go as fast as you can. In the spirit of friendly competition, post your results to the A3 Moodle Forum.
Your code will be tested for correctness and performance against various combinations of the N, niter and the number of processors and processor geometries.
Test your code by comparing against the provided implementation. You can catch obvious errors using the graphical output (see below), but a more precise test is to compare two summary quantities reported by the simulator: the L2 norm and the L∞ norm, the maximum value (magnitude) of the excitation variable. The former value is obtained by summing the squares of all solution values on the mesh, dividing by the number of points in the mesh (called normalization), and taking the square root of the result. For the latter measure, we take the "absolute max," that is the maximum of the absolute value of the solution, taken over all points. While there may be slight variations in the last digits of the reported quantities, variations in the first few digits indicate an error.
Verify that results are independent of the number of cores and the processor geometry, by examining the summary quantities. For example, for the command line options
-n 50 -i 1000
should result in the simulator reporting the following summary quantities at the end of the simulation:
Max norm: 9.866452e-01, L2norm: 5.919411e-01
To facilitate testing, the code outputs certain information to a file called Log.txt: the number of threads, their geometry, the running time, and the summary measures. Any previous copy of Log.txt will be overwritten, so if you are doing automated testing, be sure to rename the files between invocations. We will use the log in autograding so do not change the file Report.cpp as doing so could cause your assignment to be graded incorrectly.
The code and Makefile have been set up to enable you to compile without MPI, which may come in handy when debugging. To compile without MPI, specify following make command line argument:
no-mpi=1
This setting defines the _MPI_ macro which causes certain code to be conditionally compiled. To take advantage of this feature in any code you write, follow the convention used in the provided starter code.
As mentioned previously, the code includes with a plotting capability to observe the simulation dynamics which can be helpful when debugging. The plotter (splot.c) interfaces with gnuplot, which is freeware. Note that two entries are provided, one to the provided multidimensional array implementation, and another to support flattened arrays.
Remote visual display can be slow, so either work from a campus machine, or increase the frequency to at least 20 (-p 20). The summary statistics may be more useful than plotting in some cases. If a display window does not appear on your screen, then your ssh display settings are not set correctly. If you are connecting to the remote machine from a Linux platform using ssh, use the -X option:
% ssh -X yourlogin@ccom-bang-login.ucsd.edu
If you are connecting from a Windows platform, and are using a 'secure shell client' AND 'exceed' (or xwin32, or cygwin) to log into a remote machine you must ensure that 'X11 tunneling' is set. To do this, you must have installed Cygwin /X with X11.
The simulations will produce a spiral pattern that evolves with time. However, if you set the number of iterations (-i) to a sufficiently large value, the organized spiral pattern will break up. This indicates non-physical behavior, and the length of time that the simulator produces physically meaningful results depends on the mesh size N.
Be sure that, while collecting performance data, that you have not enabled plotting (-p) or statistics reporting (-s).
Note that the plotter works on 1 core only, so if you want to use the plotting capability on more than 1 core, you will first need to gather all the data onto one processor before plotting. This capability will not be graded, and we encourage you to collaborate on this effort. The techniques will be discussed in class an entail collecting the solution onto one processor using an MPI Gather operation (see links to documentation below), taking care not to plot ghost cells.
Due to an interaction between OpenMPI and Unix Pipes, we need to specify an additional command line to mpirun:
mpirun -np 4 --mca mpi_warn_on_fork 0 apf -n 100 -t 400
If you don't use the -mca command line argument, then you will get a large warning message beginning with the following text: "An MPI process has executed an operation involving a call to the "fork()" system call to create a child process." We will ignore this error but if you become aware of any problems, post to the A3 forum.
Alternatively you may set the following shell environment variable before running mpirun (e.g. via your shell startup scripts):
export OMPI_MCA_mpi_warn_on_fork="0"
OR create a user-level configuration file $HOME/.openmpi/mca-params.conf containing the following single line:
mpi_warn_on_fork = 0
Adjust the iteration count to keep the running times to within about 30 seconds. Use the normal batch queue on Bang to collect timings. Use the interactive queue to debug your code and to tune performance.
To take timings, use MPI's timer function MPI_Wtime() to measure wall clock time. MPI_Wtime() reports time in seconds and its man-page is available using the man command. To measure time, take the difference in times sampled by two successive calls to MPI_Wtime():
        double t0   = MPI_Wtime();
        // some code....
        double t1   = MPI_Wtime();
        double time = (t1-t0);
Recall that the running time of the application is that of the last processor to finish. Don't time individual iterations, but rather, time an entire run, but excluding initialization, calls to MPI_Init() and MPI_Finalize() and any other activities that are not representative of a run with many iterations.
It can be difficult to measure communication times accurately, owing to the short time durations involved. Therefore, we will use an indirect measurement technique. We do this by disabling communication of ghost cells and subtracting the resultant time from that obtained from a run that includes communication. The -k command line option (cmdLine.cpp) can be used to measure communication using the indirect method; when the option is asserted, your code should disable all MPI calls that handle ghost cell communication (e.g. Send, Isend, Ireceive and Receive), as well as any code needed to pack and unpack message buffers. Do not disable the calls to MPIInint and MPFinalize as these are needed to enable your program to run under MPI. Similarly don't remove any other message passing calls that don't involve the ghost cell communication directly but are essential for the correct operation of your code. Note that, when you shut off ghost cell communication, your code will produce incorrect results. This is to be expected.
Although Bang provides exclusive access to allocated processors, the Infiniband interconnect is a shared resource. Thus, if you run on one node, you'll observe no contention from other jobs, but on two or more nodes you'll observe the effects of switch contention. To reduce the effects of switch contention run the program at least 3 times (for each input size and number of cores, or any variable that affects the running time) until you see a consistent timing emerge, such that a majority of the timings agree to within 10%. If you observe greater variation, then try doubling the number of runs to see if you can obtain a better consensus. Exclude outlier timings, but note them in your report. Report the minimal running time rather than the average, as previously discussed in class.
To build the Aliev-Panfilov code to use the MPI+X programming model, specify the omp=1 option on the Make command line to assert the openmp option for the compiler and to cause certain code to be compiled that's needed when using OpenMP to implement multithreading:
make omp=1
As discussed in class, when we run under the MPI+X model, each node will run either 1, 2, or 4 processes. By comparison, in the "flat" MPI model, we CORE will run 1 process.
Each process in the MPI+X model will spawn threads to compute the assigned workload. Normally, the total number of threads per node will not exceed the available number of cores. In our case, the product of the number of processes per node and the number of threads per process (as determined by OMP_NUM_THREADS) will not exceed the number of cores.
The run in MPI+X mode, modify the parallel environment (PE) line in the batch submission script. With flat MPI, this line is as follows
#$ -pe orte #MPI processes
For this environment, the default processor "allocation_policy" used by job scheduler is called "fillup," which allocates cores to "fill up" a node before proceeding to the next one. We have set up alternative environments where the job scheduler fills up only part of the node, that is, a certain number of processors per node = "ppn."
There are also orte environments for 2, 4 and 8 processes per node:
orte_smp_2ppn, orte_smp_4ppn, orte_smp_8ppn
#$ -pe orte_smp_1ppn <#MPI processes>
#$ -pe orte_smp_4ppn 8
#$ -pe orte_smp_1ppn 1
#$ -pe orte_smp_2ppn 2
#$ -pe orte_smp_4ppn 4
#$ -pe orte_smp_8ppn 8
#$ -pe orte_smp_1ppn 4
#$ -pe orte_smp_2ppn 8
#$ -pe orte_smp_4ppn 16
#$ -pe orte_smp_8ppn 32
To learn more about SGE's policies do man sge_pe and read the section about "allocation_rule" that explains the various options.
Explain how your design decisions affected the observed performance.
Take care in how you plot your data, only plotting what's necessary to get your points across, and choosing log and linear plotting axes carefully. You must also include any plotted data in tabular form. Put tables in an Appendix that take up for than about 1/3 of a printed page.
If you are running out of time, put more effort into the writeup and your analysis rather than trying yet another performance enhancement. It can take time to collect, tabulate and plot results, as well as offer a reasonable explanation. We prefer a deeper analysis in voling a few program optimizations over a shallower analysis over a larger number of optimizations. Spend more time discussing the optimizations that made a difference and less on those that made less of a difference. Negative results are also valid and especially valued if you carefully document them, with the underlying causes, or best guesses if the causes are not clear.
Cite any written works or software as appropriate in the text of the report. Citations should include any software you used that was written by someone else, or that was written by you for purposes other than this class.
Your turnin must also include two important documents:
These documents are required, as the turnin process will not complete without them. Blanks for the self evaluation and MEMBERS files are available in the turnin directory, $PUB/turnin Empty forms, or forms not properly filled out, will result in a 10% penalty being assessed, in addition to holding up the grading process.
The turnin script will try to compile your project before letting you submit your assignment, so be sure to include a Makefile. When grading your assignment, we will substitute our own versions of the files that we asked you not to modify, as noted in the list above. Thus, any changes you made to these files will be lost during the grading process. If you feel that you need to make certain changes to these files, discuss them with us and also mention the changes in your writeup. We can manually test your assignment if necessary.
Don't wait until the last minute to attempt a turnin for the first time. The turnin program will ask you various questions, and it will check for the presence of certain required files, as well as your source code. It will also build the source code if you like, to catch any obvious build errors. Try out the turnin process early on so you are sure that you you are familiar with the process, and that all the required additional files are present. The turnin procedure will be available about a week before the deadline.
Your grade will depend on 3 factors: performance and correctness; explanations and insight into how you realized your reported performance. In determining your grade for the assignment, explanations and insight will be emphasized more heavily than performance itself, provided you were able to get your code to scale.
There is a nice tutorial with some worked examples. Man pages for the MPI calls may be accessed with the man command and they are also available On-line. More extensive documentation can be found at http://www-cse.ucsd.edu/users/baden/Doc/mpi.html. The on-line man pages for MPI calls used in this assignment appear below.
| MPI _Init | Initialize the MPI environment. Call this prior to making any MPI calls. |
| MPI_Finalize | Exit the MPI environment. Call this function before exiting your program. |
| MPI_Comm_size | Queries the total number of processes use in this program invocation. |
| MPI_Comm_rank | Queries this process's unique identifier, an integer called the rank |
| MPI _Send | Sends a message to another process, a return signifies that the message buffer may be reused. |
| MPI_Recv | Receives a message from another process, a return signifies that the message has been received. |
| MPI_Isecv | Immediate form of Send. A return does not signify that the message has been sent, that is safe to reuse the buffer. For this you need to use MPI_Wait() |
| MPI_Irecv | Immediate form of Receive. A return does not signify that the message has been received. For this you need to use MPI_Wait() |
| MPI_Wait | Return indicates that a previously posted Irecv (or Isend) has completed |
| MPI_Wtimer | Timer. |
| MPI_Gather | Gathers data from all processes onto the designated root process. All processes contribute the same amount of data. A collective routine, which all processes in the communicator must call. |
| MPI_Gatherv | The "Vector" version of Gather(). Unlike Gatherv(), processes may contribute different amounts of data. Requires a call to Gather() to determine the sizes of the gathered data contributions. A collective routine, which all processes in the communicator must call. |
| MPI_Barrier | Blocks calling process until all processes have checked in. A collective routine, which all processes in the communicator must call. |
Copyright © 2012 Scott B. Baden [Sun Nov 4 16:02:47 PST 2012]